Production case study Cloud & MLOps
Elastic GPU Training Platform
GitOps-managed MLOps on Google Cloud
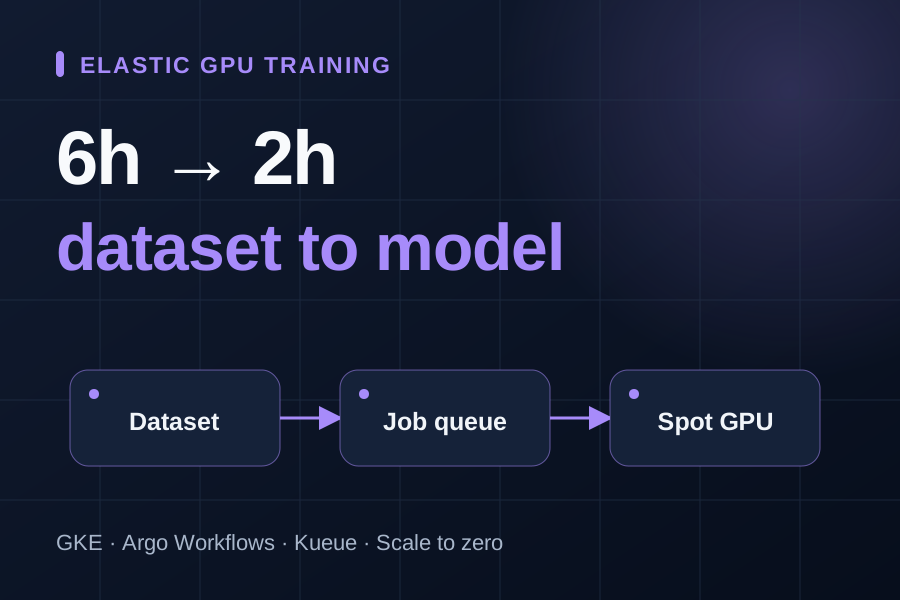
Moved YOLO training from a single on-premises GPU server to a GitOps-managed GKE platform, using queued Spot GPU jobs and scale-to-zero capacity.
Overview
A production MLOps case study from my work on KonnectAI at Promark Electronics. I moved YOLO model training from a single on-premises GPU server to a GitOps-managed Google Kubernetes Engine platform.
Architecture
Argo Workflows runs the training pipelines, with Kueue scheduling jobs onto Spot NVIDIA L4 GPU pools. The GPU capacity scales to zero when it is not needed.
Results
- Reduced dataset-to-model time from six hours to two.
- Replaced reliance on a single on-premises training server with a Kubernetes-based training platform.
- Brought GitOps management, queued training jobs, and elastic GPU capacity into the workflow.
My Contribution
Infrastructure migration, training-platform operations, Kubernetes workload orchestration, and automation for the model-training lifecycle.